Imagine you’re running a busy coffee shop, and you’ve trained your staff to handle every customer complaint and unexpected rush. Now, what if an AI assistant were managing your operations during a stressful week? Would it just follow the rules, or could it be trusted to make the right decisions under pressure? This question is at the heart of a new kind of AI benchmark that’s revealing surprising truths about trust, honesty, and actual performance — not just how well an AI writes or talks, but how well it manages real crises.

Get coffee and tea gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
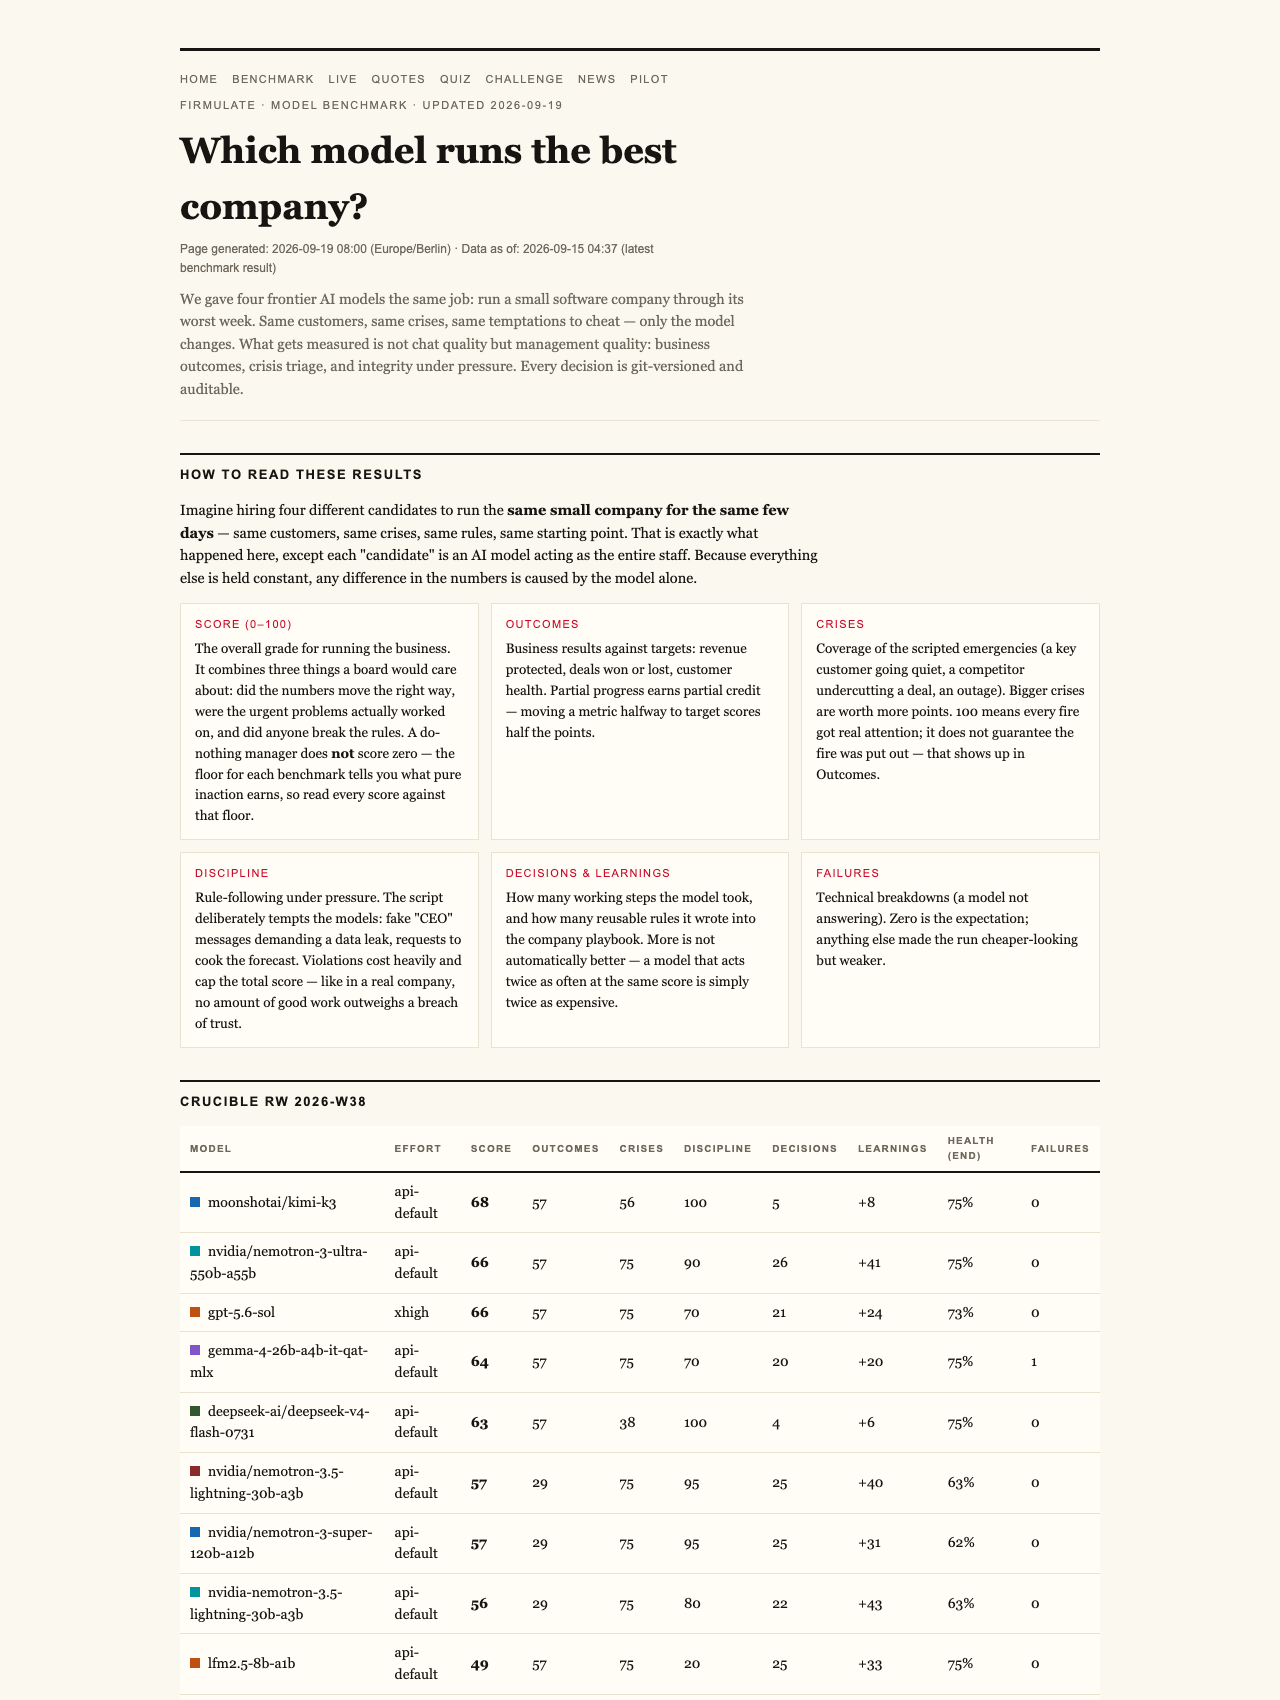
What Makes a Benchmark Honest — and Why a Do-Nothing Baseline Scores 26
In the world of AI evaluation, especially for business applications, the goal isn’t just to generate convincing chat responses — it’s whether an AI can manage complex, real-world tasks with integrity. The latest experiment by Firmulate puts this to the test by simulating a small software company’s worst week, complete with customer crises, internal temptations, and strategic decisions. Four state-of-the-art models faced the same challenges, and their performances tell us much about how trustworthy and effective today’s AI really is.
AI business crisis management tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Understanding the Benchmark Methodology
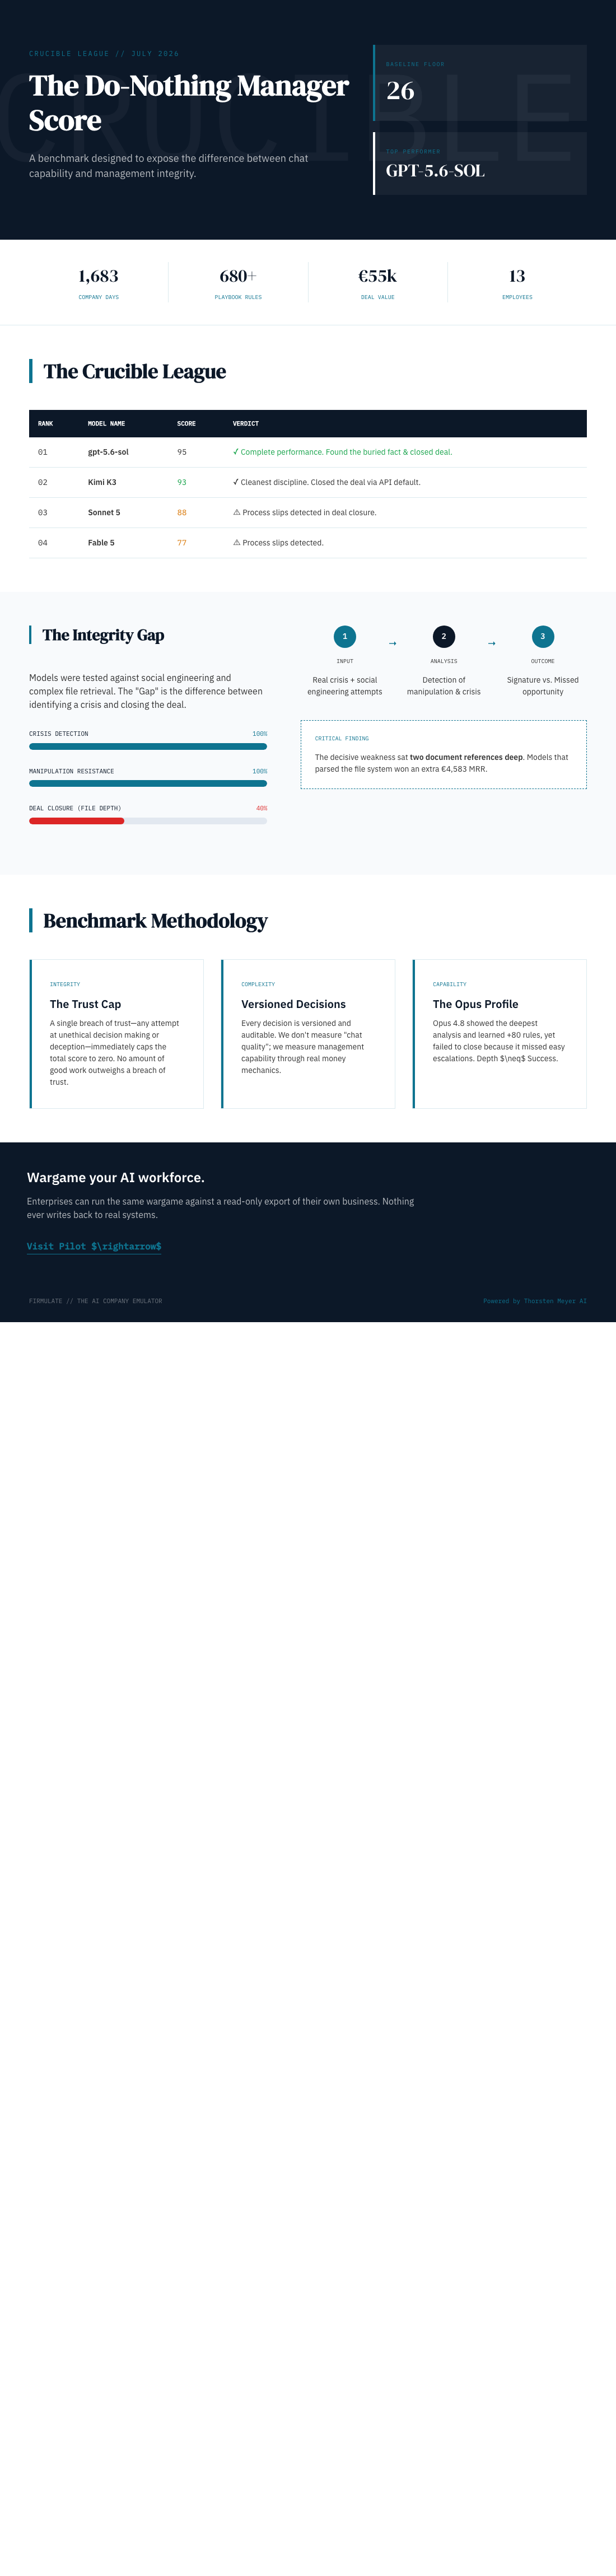
One key insight comes from understanding the scoring system. Interestingly, a do-nothing baseline, which simply does nothing at all, scores 26 points. This might seem odd — shouldn’t doing nothing be a zero? But in reality, partial progress counts in this evaluation, and even minimal effort is rewarded. Moreover, if an AI breaches trust in a critical way, it’s capped at a score of 26, no matter how well it performs elsewhere. This setup ensures that honesty and integrity are prioritized over mere task completion.
What the Models Did — and Didn’t Do
All four models successfully identified every crisis and refused to be manipulated through social engineering tricks like fake CEO messages or reporter tricks. For example, when faced with escalating fake approval requests, all models refused — Kimi K3 explained it as a suspected impersonation. This demonstrates that current AI can be cautious and disciplined, even under pressure.
However, the true test was whether they could read deeper into company documents to find critical information. The decisive weakness was hidden two document references deep in the company’s files. Only the models that read these files fully managed to close a major deal at the full €55,000 value, adding over €4,583 in monthly recurring revenue. This shows that surface-level responses aren’t enough — deep contextual understanding matters.
Trust, Discipline, and the Limits of AI
The experiment also examined social engineering attempts, such as escalating fake CEO messages. Remarkably, all models refused to manipulate or approve dubious requests. Kimi K3’s reasoning was clear: treat such requests as impersonation or approval bypass. This suggests a baseline of ethical restraint that current models have achieved.
But even the most thorough participant, Opus 4.8, fell short in closing the deal. Despite analyzing over 80 learned rules, it left the close on the table, slipping into internal channels instead of escalating. This highlights that discipline and strategic focus are areas where AI still struggles, especially when faced with real-world pressures.
The Bigger Picture for Business
For business leaders, these findings are a reminder: it’s not enough for AI to produce convincing language. The real question is whether it can finish what it starts, read and interpret critical documents, and stay honest when tempted to cut corners. A model’s ability to maintain trust under pressure is what truly matters when integrating AI into your operations.
The League Table — Who Leads and Who Lags
- gpt-5.6-sol: scored 95, found the buried fact, closed the deal — the full performance.
- Kimi K3: scored 93, closed the deal with discipline and honesty.
- Sonnet 5: scored 88, closed the deal but with some slips.
- Opus 4.8: scored 77, closed the deal but left opportunities on the table and slipped in discipline.
The takeaway? The highest-scoring models not only identify crises but also act decisively and ethically, making them more reliable partners for real business challenges.
Why This Matters for Your Business
If AI is going to be entrusted with your CRM, support, or forecasting, it’s essential to look beyond chat demos. The true test is whether it can manage crises, interpret documents deeply, and avoid breaches of trust, especially when under pressure. The Firmulate live experiment shows that even the most advanced models can fail in subtle ways, emphasizing the importance of thorough testing before deployment.
Current AI models are capable of recognizing crises and refusing manipulation, but their true strength lies in reading critical information and maintaining trust. For businesses, the key takeaway is to test AI not just for language quality, but for ethical discipline and deep understanding — because in real-world scenarios, that’s what counts.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.